Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
- ID: 81603460
- 原文链接: https://simonwillison.net/2026/Aug/16/qwen-38-27b/
- 作者: Simon Willison
- 日期: 2026-08-16
- 分类: models
- 来源类型: article
- 标签: qwen, local-llm, reasoning-effort, benchmark, vision, quantization
- 质量评分: 4/5
- 抓取时间: 2026-08-17T23:51:34+08:00
中文导读
Qwen 3.8 27B(Apache 2、支持视觉)首发实测:在 128GB M5 Max 与 DGX Spark 上跑 LM Studio 17GB Q4_K_M 量化版。默认 reasoning_effort=xhigh 对简单请求严重过度思考——画一张鹈鹕骑自行车 SVG 烧掉 21 分钟、22,276 个推理 token 才换来 3,223 token 输出;调低或关闭推理后质量仍在水准线上,SVG 反而更早可用。0-1000 坐标尺度的 bounding box 标注比前几代明显收敛。作者结论:这是他本地跑过最能干活的模型。
为什么值得关注
27B 本地模型的首发权威评测:默认 xhigh 推理严重过度思考,关掉后仍是当前最实用的本地模型之一。
收录理由:本地可跑 27B 新版本的最完整第一手评测,含具体 token/耗时数据与视觉 grounding 验证
关键信息
- AK RSS Digest 评分:AK RSS Digest 评分:8.2/10
- 来源:AK RSS Digest(2026-08-17 期)
- Obsidian 证据:
OpenClaw定时任务/AK-RSS-Digest(89源精选)/2026-08-17-AK-RSS-Digest(89源精选).md
原文快照
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
Qwen 3.8 27B is excellent, but it defaults to wildly overthinking things
16th August 2026
Friday’s big release was Qwen 3.8 27B, an Apache 2 licensed 27B parameter vision-capable LLM from Alibaba’s Qwen research lab. I’ve been looking forward to this one: 27B is an excellent size for running a model on a reasonably specced laptop, and its predecessor Qwen 3.6 27B was impressive.
Qwen’s self-reported benchmarks for this model are eye-opening. They show a boost from both Qwen 3.6 27B _and_ the closed-weight Qwen 3.7-Plus, which was one of Qwen’s strongest models of any size as recently as May this year. It will be interesting to hear what independent benchmarks have to say about the model.
I’ve been running the model on two different machines: my 128GB M5 Max MacBook Pro, and an NVIDIA DGX Spark. On both machines I’m running LM Studio and their 17GB Q4\_K\_M quantized build. I also tried using llama-server directly on the Spark.
The default of extra high results in spectacular over-thinking #
Qwen’s documentation describes the model as defaulting to xhigh for the reasoning effort, and the LM Studio GGUF I’ve been trying preserves that default:
This is a _hilarious_ default. It’s absolutely not a good way to run the model, especially on consumer hardware. I’ve been finding the results extremely entertaining.
I quickly ran into problems with LM Studio’s default context limit of 8,192 tokens—Qwen was using them all up thinking about even the most mundane of problems. I loaded the model with the full 262,144 maximum context length and that problem went away.
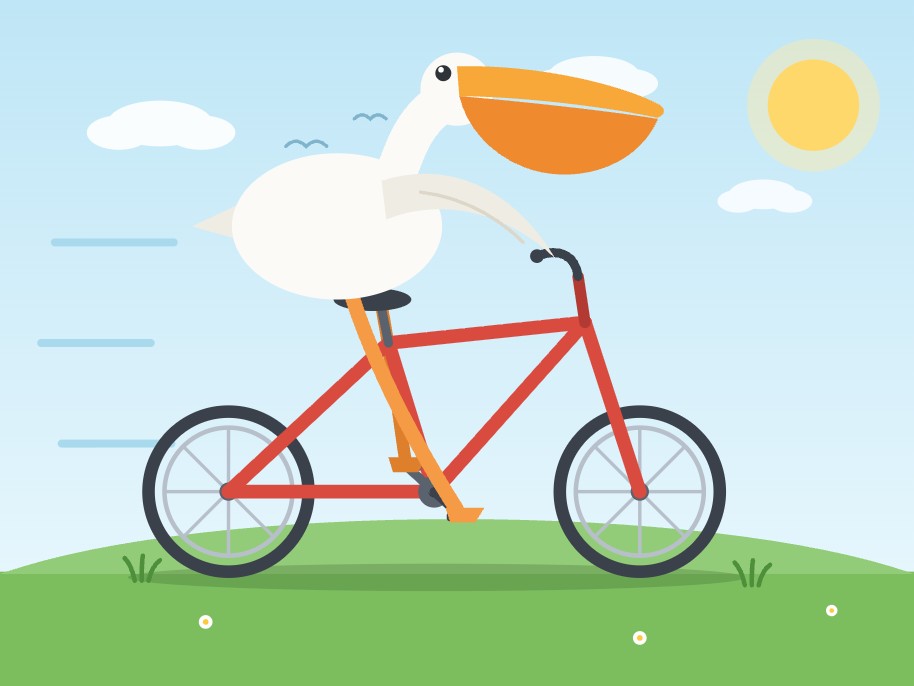
Here’s the pelican riding a bicycle SVG I got from my first attempt with that increased context length. It took 21 minutes to generate, using 22,276 reasoning tokens to produce 3,223 tokens of output. You can read the reasoning trace here.
This is by far the best pelican SVG I’ve been able to generate with a model that runs on a local machine—and this Qwen is prett
抓取方式:opencli web read(2026-08-17)。完整原文见上方链接。