Creepy Crawlies: AI Crawler Load on git.kernel.org, With Hard Numbers
摘要中文导览(来自条目评分时的双语摘要,基于原文提炼):
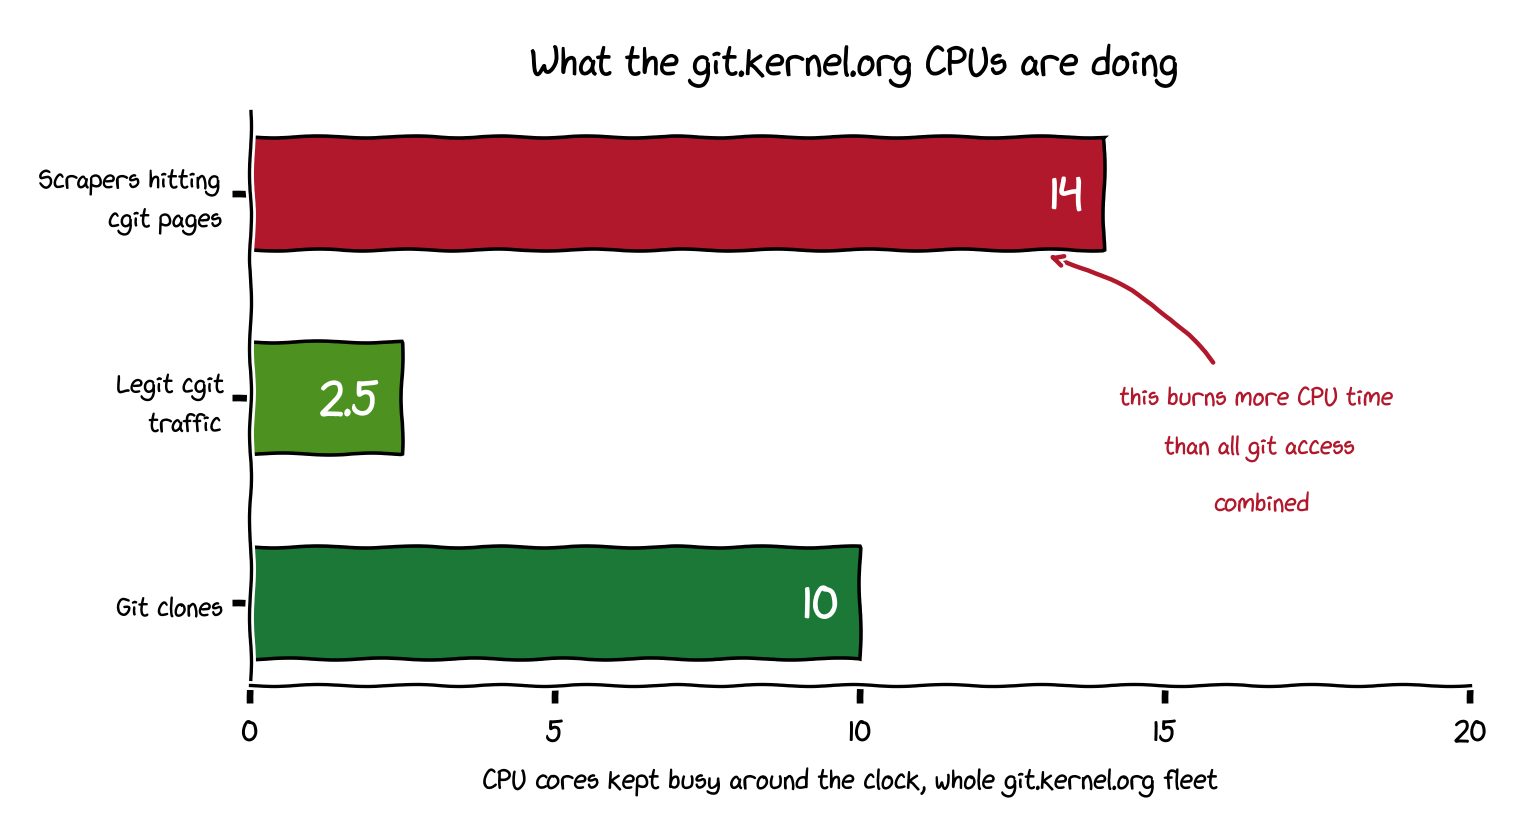
- kernel.org 的 Konstantin Ryabitsev 公布 AI 爬虫对 git.kernel.org 负载的硬数字:渲染 commit 页面给爬虫消耗的 CPU 已超过所有正常访问(含 git clone)的总和——5 个地理分布节点共 90 核中,任何时刻有 14-16 核纯粹在为爬虫渲染 HTML,约占容量 20% 且呈波峰式冲击。荒诞点在于这些数据一条 git clone 就能全部拿走,但爬虫坚持逐 commit 抓 HTML:linux.git 有 148 万 commit 加 922 个 fork、patch/plain/diff 视图,可枚举 URL 空间近乎无限。对抗史很典型:UA 封禁导致伪装浏览器;封 IP/ASN 后爬虫转向住宅与移动代理轮换;Anubis 工作量证明清净数月后难度 4 提到 5 也被解,每天 600 万次 commit 请求中 66% 被挡下、33% 算完哈希进来;合法请求估计仅占全部流量约 2%,接下来只能靠关功能、减少可爬 URL 止血。
文章信息
- 作者: Konstantin Ryabitsev
- 发布: 2026-08-29
- 原文链接: https://people.kernel.org/monsieuricon/creepy-crawlies
- 标签:
ai-crawlersweb-infrastructureanubisproof-of-workdata-scraping
原文摘录(开头)
2026年8月29日
You've probably heard me complain about the “AI crawlers” before, but now I actually have some hard numbers I can put up to show their impact. In a few words, it's bad enough to create a constant “background radiation” of system load, permanently tying up a chunk of capacity spent on producing output that is only useful for a single purpose — feeding a learning model.
TL;DR: we spend more CPU cycles rendering commits for scrapers than we spend on all other kinds of legitimate access, including git clones. At any one time, across 5 geo-distributed nodes, there are 14 CPU cores doing nothing but rendering git commits as html.
Linux development happens in the open — from git repositories you can clone, to discussion archives you can follow in real time. To a large language model, this is a goldmine of learning data, because all of this is not only immediately available, but is easy to filter in order to guarantee pure unadulterated pre-AI content. Training an LLM on content produced by the LLM gives it the equivalent of a digital prion disease, so when a source is guaranteed to be LLM-free, like the entire history of kernel commits, it's worth its weight in gold as a source of training data.
Summary (EN)
kernel.org's Konstantin Ryabitsev publishes hard numbers on AI crawler load: rendering commit pages for scrapers now consumes more CPU than all legitimate access including git clones — 14-16 of 90 cores across 5 geo-distributed nodes at any moment, about 20% of capacity in spiky bursts, despite the entire history being freely clonable. The arms race is textbook: UA blocking led to browser spoofing; IP/ASN blocking to residential proxy rotation; Anubis proof-of-work held for months before difficulty 5 fell, with 66% of 6M daily commit requests blocked and 33% grinding through the hash. Legitimate traffic is estimated at only ~2% of the total.
Obsidian 证据摘录
入选自 Obsidian《ClawFeed 24小时高价值一览 · 2026-08-31》第2篇:少见的带硬数字的 AI 爬虫负载抱怨。