How I think about reducing AI costs
- ID: 2057fe55
- 原文链接: https://martinalderson.com/posts/how-i-think-about-reducing-ai-costs/
- 作者: Martin Alderson
- 日期: 2026-08-16
- 分类: infra
- 来源类型: article
- 标签: ai-costs, inference, mcp, token-optimization, caching, finops
- 质量评分: 4/5
- 抓取时间: 2026-08-17T23:51:34+08:00
中文导读
有客户账单实测背景的降本四层 checklist:先按模型与 cached/uncached input/output 拆账(多数团队连 coding agent 支出都没统计);同 provider 内旧型号换同档新型号常能砍一个数量级;token 大户迁到本地/开源权重托管、其余留在闭源厂商;最后做 agent 优化——prompt 别塞整篇文档、工具返回 JSON 限长(一个 MCP server 带 142 个工具定义、每次请求先烧约 21k token)、长 run 末尾的 tool failure 会触发 cache read 成本雪崩。QuickBooks MCP 一段可直接当工具设计检查模板。
为什么值得关注
AI 账单降本的工程化四层下钻:从拆账、换模型到 agent 工具返回限长,每层都有实测数字。
收录理由:给 AI 重度使用团队的降本框架,含具体工具设计反例与账单拆法,可直接套用
关键信息
- AK RSS Digest 评分:AK RSS Digest 评分:7.8/10
- 来源:AK RSS Digest(2026-08-17 期)
- Obsidian 证据:
OpenClaw定时任务/AK-RSS-Digest(89源精选)/2026-08-17-AK-RSS-Digest(89源精选).md
原文快照
How I think about reducing AI costs
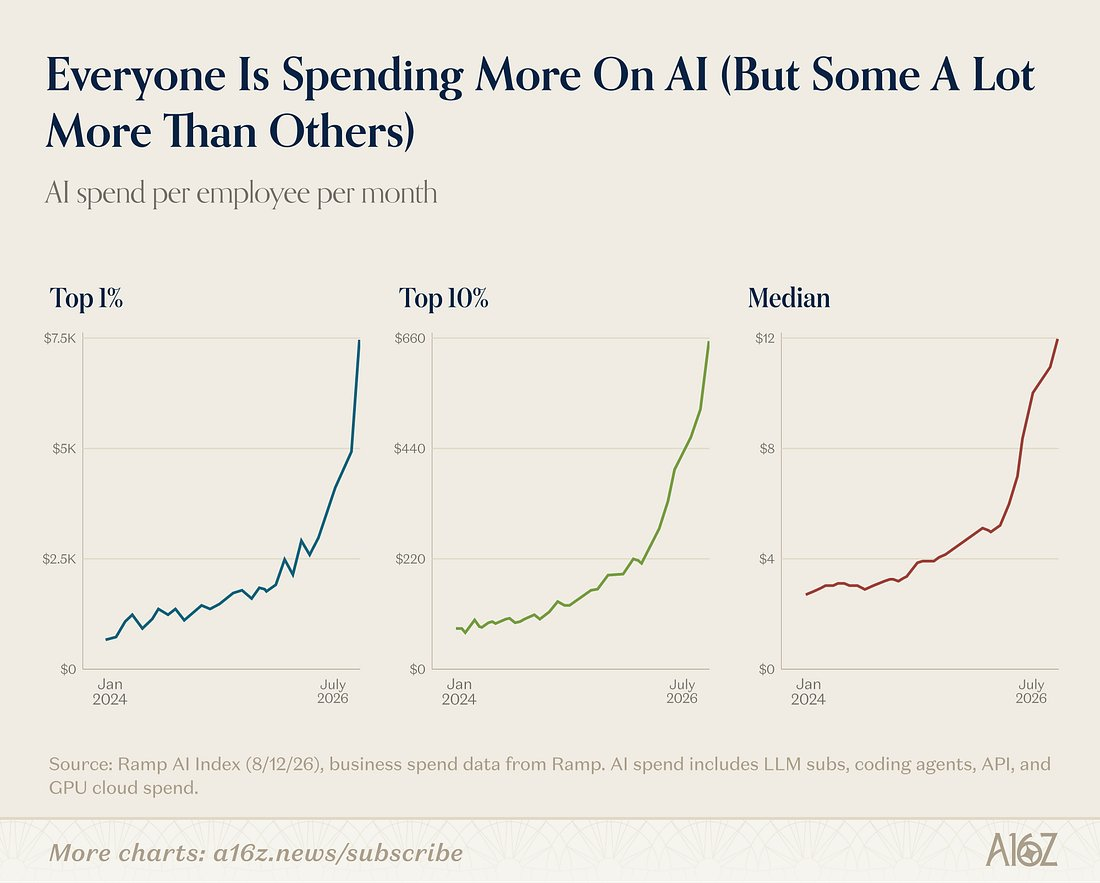
AI inference costs are something I've been writing about for a while. It's clear that for many companies this is becoming a huge problem:
I've heard from a lot of readers that reducing this cost is becoming a hot topic internally.
So, here's _how_ I think about this problem at a high level.
Audit costs
You _need_ to have a good handle on what is driving your bill. I've met a lot of companies who have a pretty fragmented understanding of the costs - they can be siloed over many different teams, business units and roles.
At a minimum, you need to know - business-wide - how much you are spending on AI _and_ importantly, key stats on how that breaks down. There are two main dimensions on this.
Firstly, the model in use. I see _a lot_ of people running ancient, poor value for money models. The tech debt is real here! For example, GPT-4o is $2.50/$10 per million tokens, but is _drastically_ worse than GPT-5.6 Luna, which is 10% of the cost. It's _really_ important to know what models you are using.
The second dimension is how your spend breaks down by the three main components of token costs - cached input, uncached input and output. As I wrote recently, with agents the distribution of these costs is rarely what you'd expect.
Keep in mind you need to collect this data for _all_ your usage. This includes LLM usage via API or similar, coding agents and any other autonomous/business agents you have running. A key mistake I see is people focussing on their API spend, but not looking at their enormous coding agent spend for their dev team, which is out of control, or vice versa.
Low hanging fruit
Once you've got this done, the next thing is to look for obvious cost savings. As I mentioned before, it's usually quite easy to swap out legacy models with something cheaper _from the same provider_ - though it should involve a verification stage, because you can risk regressions this way. It can result in a lot of the 'hacks' you've perhaps used for a less intelligent model backfiring.
The other key thing to look for is models that are 'overpowered' for the us
抓取方式:opencli web read(2026-08-17)。完整原文见上方链接。